Reducing Shipping Errors Through Automated Quality Control
How smarter fulfillment controls catch costly mistakes before they reach customers and create a more scalable operation
Shipping mistakes look small until you calculate the refunds, replacement orders, support time, lost inventory, and customer trust behind them. Reducing shipping errors through automated quality control creates a systematic way to catch problems before packages leave the operation. The result is more accurate fulfillment, clearer performance data, stronger customer retention, and an operation that can handle growth without multiplying mistakes.
The Real Cost of Shipping Errors
A shipping error rarely costs what it appears to cost. A $12 item shipped incorrectly does not create a $12 problem. It creates a chain of work. Someone identifies the issue. Customer service responds. Warehouse staff investigate. Inventory gets corrected, assuming anyone notices the discrepancy. Then there may be a refund, replacement, return label, extra packaging, and another shipment. That same chain can begin with the wrong product, wrong quantity, damaged goods, or bad packaging. Incorrect labels and addresses create similar problems. So do missed instructions, especially for orders requiring specific handling. The useful question is: What does one error actually cost from beginning to end? Include direct expenses and the less-visible labor surrounding them. Measure warehouse rework, support contacts, replacement freight, refunds, packaging, returns, and inventory adjustments. Then account for customer consequences. A customer expecting an effortless delivery suddenly has another task. They may contact support twice. They may leave a poor review. More importantly, they may quietly decide not to order again. That connects fulfillment directly with the reasons customers leave. This is where small percentages become deceptive. Suppose 99% of 1,000 monthly orders are correct. Ten errors may seem manageable. At 50,000 orders, the same accuracy produces 500 problems. If each error costs $35 after labor and reshipping, that's $17,500. That excludes lost repeat purchases and leadership time spent investigating recurring failures. So measure errors two ways: as a percentage and as financial impact per order. Percentage shows operational quality. Dollars show whether fixing the problem deserves investment. Useful measurements include:- Order, picking, and packing accuracy rates
- Return reasons and cost per shipping error
- Rework minutes and customer contacts per error
- Error rates by SKU, employee, shift, warehouse zone, and carrier
Building Automated Quality Control Into Fulfillment
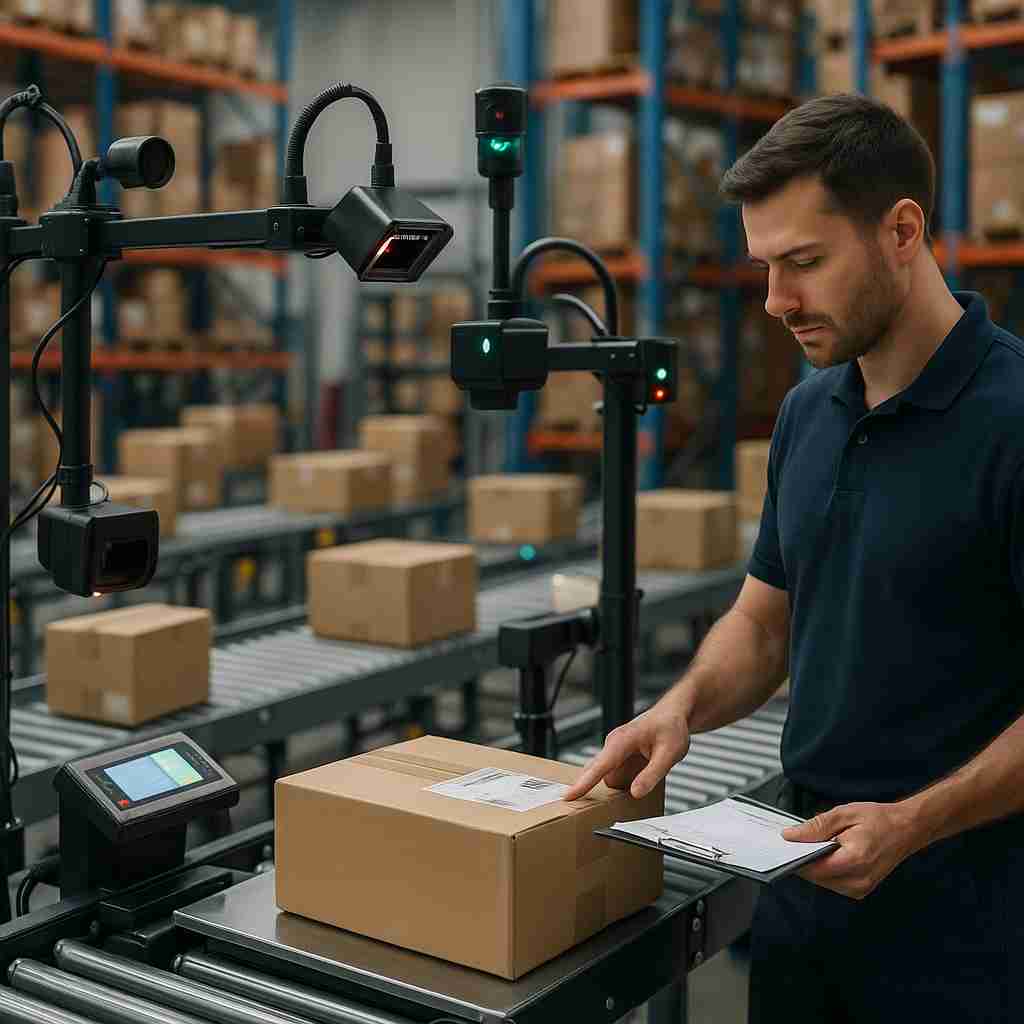
Once you know what errors cost, the next move is placing controls where mistakes can actually be stopped. That is different from simply automating fulfillment. Automation moves work. Automated quality control checks whether that work produced the expected result. An order enters through the ecommerce platform, then flows into ERP and warehouse systems. Inventory gets allocated against current records. Before picking begins, rules can flag unavailable inventory, unusual quantities, conflicting instructions, or suspicious order combinations. During picking, barcode scans can verify the location and SKU. Guided picking or pick-to-light systems can direct workers toward the correct item. Quantity validation confirms that three units ordered means three units picked. The objective is simple: make the correct action easier than the incorrect action. Verification adds another checkpoint before packing. The system compares scanned products against the order record. For operations with suitable products and sufficient image data, computer vision can identify obvious item or quantity mismatches. Image capture can also document what entered the package. Packing creates another useful control point. Expected package weight can be calculated from reliable SKU master data. The measured weight is then compared against an acceptable tolerance. Dimensional checks can identify the wrong carton or unexpected packaging conditions. Next comes shipping data. Address validation can identify incomplete or inconsistent destinations before labels are produced. Automated label verification can confirm the recipient, service level, tracking identifier, and order association. At carrier handoff, a final scan can establish that the verified parcel actually entered the outbound stream. This works only when systems agree. Ecommerce, ERP, warehouse management, automated shipping software, and inventory records need dependable synchronization. Bad master data simply allows automation to make bad decisions faster. SKU dimensions, weights, barcodes, addresses, and inventory mappings must stay clean. SOPs should define what happens when checks fail. Permissions should prevent unauthorized overrides. Testing should cover normal orders and edge cases. Exceptions need clear human escalation instead of forcing questionable orders through. Choose controls using four practical questions: How frequently does this error occur? What does each occurrence cost? How difficult is prevention to implement? Do you have reliable data to support the check? A high-cost, frequent error with strong data deserves priority. An expensive technology searching for a problem does not. The useful model is automate the routine, verify critical points, and escalate abnormalities. People remain essential where context and judgment matter. Better controls simply ensure they spend less time discovering preventable mistakes after shipment and more time resolving meaningful exceptions.Turning Error Data Into Continuous Improvement
Once those quality controls are running, something useful happens beyond catching bad shipments. They start producing evidence about why errors occur. That evidence turns quality control into a management system. Dashboards can show error rates by SKU, shift, location, error category, and order type. Exception logs provide the underlying detail. Leaders can then compare current performance against baseline measurements and established control limits. The key is separating the symptom from the cause. Ten wrong-item shipments do not necessarily mean employees need another verification step. The warehouse layout may place similar products together. Packaging may look nearly identical. Inventory records could be inaccurate. Procedures may be ambiguous. Training could be inconsistent. A system configuration might even be directing workers toward the wrong location. This is why every exception should not trigger another automation. Adding controls without diagnosis can increase costs while preserving the underlying problem. A recurring operational review can use a simple framework:- Frequency: How often does the error occur?
- Severity: What does each occurrence cost financially and operationally?
- Cause: What evidence identifies the underlying failure?
- Corrective action: What specific change should remove or reduce that cause?
- Owner and deadline: Who is accountable, and by when?
- Measured outcome: Did the error rate actually improve?